Local AI infrastructure
Local AI Server Guide 2026: Hardware, Cost, VRAM & Setup
To build a local AI server, start with the model and workload, size the memory it needs, then choose compute, storage, networking, runtime, and security around that requirement. Do not start by buying the fastest GPU: a useful AI server is a complete system that can load the model, keep agent state safe, recover after failures, and stay reachable when you need it.
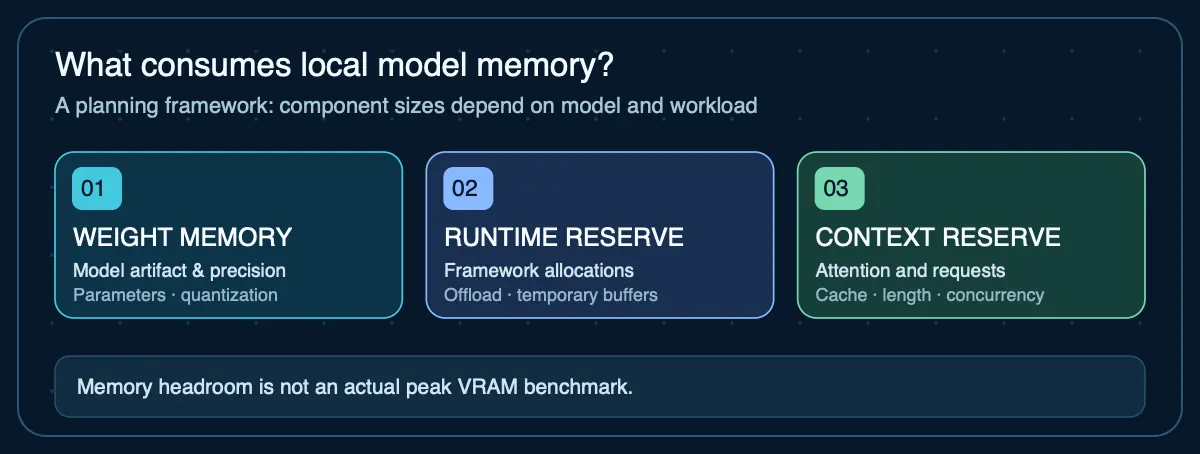
Size the model before you buy the server
Estimate the VRAM and memory requirement first, then compare local hardware with cloud cost.
Can I build my own AI server?
Yes. An AI server can be an existing desktop running a local-model runtime, a Mac with large unified memory, a Linux workstation with one GPU, or a dedicated multi-GPU server. The correct design depends on model size, throughput, uptime, power, networking, and whether the same machine also runs agents, databases, browsers, and other tools.
Would you rather rent than build? An AI dedicated server is an entire physical server reserved for one customer; that guide compares it with a VPS, GPU cloud and hardware you own.
What hardware does a local AI server need?
A local LLM server needs enough memory for the model weights, context and runtime overhead, plus system headroom for the operating system and any agents or databases running beside it. For GPU inference, VRAM is usually the first hard constraint. On Apple silicon, unified memory is shared by the CPU and GPU, so the usable model capacity comes from the total memory budget rather than a separate graphics-memory pool.
The fastest way to avoid buying the wrong hardware is to size the exact model first. Use the LLM VRAM calculator and then compare the result with the model-specific hardware guides for DeepSeek, Llama, Gemma, Mistral, Qwen and gpt-oss.
AI server build profiles
These are planning profiles, not universal minimums. Use the model-memory calculator before buying hardware because quantization, context length and concurrency can change the memory requirement substantially.
| Build profile | Memory planning | Compute | Good fit |
|---|---|---|---|
| Reuse an existing machine | 16–32 GB system/unified memory | CPU, integrated GPU or Apple silicon | Learning, small models, embeddings, orchestration and low-throughput local inference |
| Single-GPU local AI server | 32–64 GB+ system RAM | One discrete GPU with enough VRAM for the target model | Regular local inference, agents that call a private model endpoint, image or embedding workloads |
| High-memory workstation/server | 64–128 GB+ system RAM | High-VRAM GPU, multiple GPUs or large unified-memory system | Larger models, longer context, heavier concurrency and more demanding local workloads |
| Multi-GPU / data-center server | Workload sized | Multiple accelerators with planned PCIe, networking, power and cooling | Training, high-throughput inference, large models or several simultaneous workloads |
1. Decide what the AI server will run
Define whether the machine will run local inference, fine-tuning or training, embeddings, image/video generation, AI agents, databases, or a combination. A server that only orchestrates agents using hosted model APIs has very different hardware needs from a server that keeps a large language model resident in GPU memory.
2. Size RAM and VRAM before choosing the GPU
Start with model size, quantization, context length and expected concurrency. If the model cannot fit comfortably in available VRAM or unified memory, faster compute will not solve the capacity problem. System RAM also needs room for the operating system, runtime, CPU offload, databases, containers, browsers, and other services.
3. Choose GPU, Apple silicon or CPU-only hardware
- Discrete NVIDIA GPU when CUDA ecosystem support and accelerator compatibility matter most.
- Apple silicon when large unified-memory configurations and efficient local inference fit the workload.
- CPU-heavy server for orchestration, small models, embeddings, databases, or low-throughput inference.
- Multiple GPUs or nodes only when the workload justifies the added power, cooling, topology, networking and software complexity.
Can I put a GPU in an AI server?
Yes, if the chassis, motherboard, PCIe lanes, power supply, connectors, cooling, physical clearance, firmware and operating system support it. High-end data-center and multi-GPU configurations require much more planning than installing a desktop GPU in a workstation. NVIDIA's server guidance specifically treats CPU capacity, system memory, PCIe topology, networking and storage as part of the GPU-server design rather than as afterthoughts.
Do I need a GPU for my own AI server?
Not always. CPU-only servers can run agent orchestration, databases, embeddings, small models and low-throughput inference. A GPU becomes more important as model size, latency requirements, training, image generation, or concurrent inference demand increases.
4. Choose an inference runtime
The runtime determines how the model is loaded, served, and managed. Common options for a local AI server include:
- Ollama: Local model management with a simple CLI and API. Good for development, single-user inference, and straightforward deployment. See the Ollama hosting guide for deployment, persistence, and security considerations.
- vLLM / SGLang / TokenSpeed: Higher-throughput serving engines designed for production inference. Better fit for concurrent users, batching, and GPU utilization optimization.
- llama.cpp / MLX: Lightweight runtimes for CPU, Apple silicon, or single-GPU inference. Good for resource-constrained setups and direct model interaction.
5. Separate model inference from agent workloads when useful
The machine running the model does not have to run every agent, queue, database, browser, or integration. A dedicated inference endpoint can serve several agent workers and lets you scale expensive accelerator capacity separately from ordinary CPU services.
6. Plan AI server storage and backups
Model files, container images and checkpoints can consume substantial storage. Keep replaceable model caches separate from irreplaceable agent state. Back up configuration, databases, credentials metadata and work products required to reconstruct the system, and leave enough free space for updates and temporary files.
7. Secure networking and remote access
Prefer private-network access for model and administration endpoints. If remote access is required, use authentication, encrypted transport, firewall rules, least-privilege users and monitoring instead of exposing unrestricted inference or management services directly to the internet.
8. Monitor memory, GPU, storage and inference
Monitor system memory pressure, GPU memory and utilization, storage, model load time, inference latency, failures, restarts, queue depth and agent-visible service availability. Capacity decisions should come from observed bottlenecks, not a generic hardware score.
How much does it cost to build your own AI server?
The useful comparison is total cost, not just the GPU purchase price. Add the computer or server, accelerator, RAM, NVMe storage, networking, power, cooling, backup hardware or cloud backup, replacement risk, and your time maintaining the system. Then compare that total with renting a VPS, dedicated server, or GPU cloud for the number of hours you actually need the workload.
Sources
- NVIDIA-Certified Systems Configuration Guide— PCIe topology, system memory, storage, power, networking and GPU-server design guidance
- Apple MLX unified memory documentation— Apple silicon CPU/GPU unified-memory behavior
- Apple Developer — MLX for Apple silicon— First-party explanation of MLX and unified-memory execution
- Ubuntu Server security documentation— Layered server-security guidance for users, firewalling and access control
Agent Infrastructure Recommendation Kit
Planning a local AI server? Document the decision before you buy
The Agent Infrastructure Recommendation Kit walks you through defining requirements, estimating memory and compute capacity, comparing local vs. cloud vs. hybrid options with documented evidence, and producing a defensible build-or-rent recommendation.
Get the Recommendation Kit — $19