Llama infrastructure
Llama Hardware Requirements: RAM and VRAM by Model Size
Llama hardware requirements vary from compact 1B and 3B local models to 70B and 405B deployments that need much more memory. The table below uses Meta's published parameter counts and AIG's shared estimator so every memory figure is computed rather than copied from a roundup.
Llama hardware requirements: quick answer
Llama 3.2 1B and 3B are comfortable local-inference candidates. Llama 3.1 8B has a 4 GB 4-bit weight floor, while 70B starts around 35 GB before runtime and context reserves. Llama 3.1 405B is firmly in multi-GPU territory.
Computed RAM / VRAM floors by model
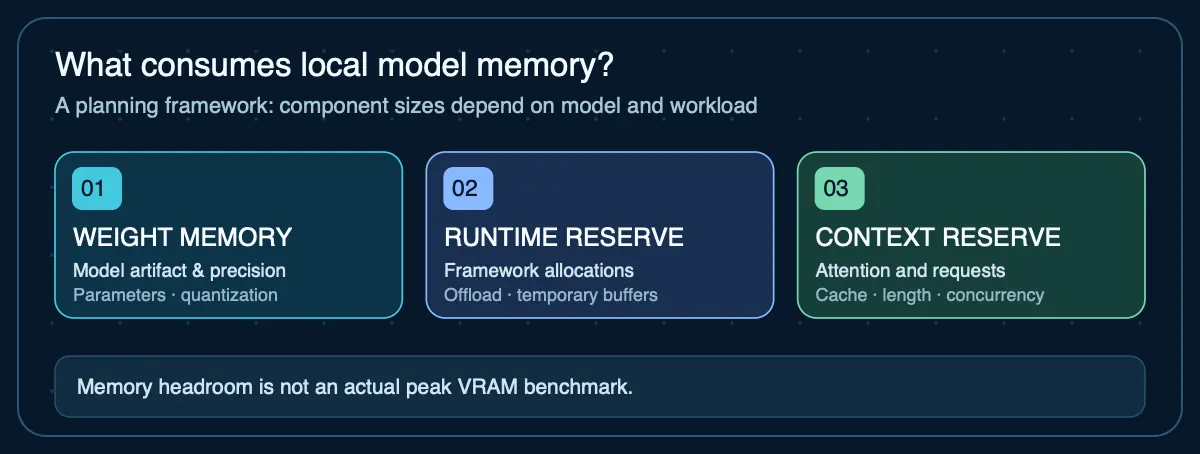
Weight memory is parameter count × bits per weight ÷ 8. The final column is deliberately more conservative: it runs the same 4-bit estimate through AIG's default 20% runtime reserve and 2 GB context/cache reserve. Neither value includes workload-specific concurrency, unusually long context, offload buffers, or multimodal activations.
| Model | 16-bit floor | 8-bit floor | 4-bit floor | 4-bit planning target |
|---|---|---|---|---|
Llama 3.2 1B 1.23B parameters | 2.5 GB | 1.2 GB | 0.6 GB | 2.7 GB |
Llama 3.2 3B 3.21B parameters | 6.4 GB | 3.2 GB | 1.6 GB | 3.9 GB |
Llama 3.1 8B 8B parameters | 16 GB | 8 GB | 4 GB | 6.8 GB |
Llama 3.1 70B 70B parameters | 140 GB | 70 GB | 35 GB | 44 GB |
Llama 3.1 405B 405B parameters · Large multi-GPU deployment class. | 810 GB | 405 GB | 202.5 GB | 245 GB |
CALCULATED. The planning target is weight floor + 20% runtime reserve + 2 GB context reserve. Validate the actual artifact and runtime before buying hardware.
Recalculate Llama for your quantization and reserves
Starts with 8B parameters. Change precision, runtime reserve or context reserve to match your deployment.
Why context reserve is manual: exact attention-cache memory cannot be inferred safely from parameter count alone. For a real deployment, measure the specific model and runtime at the context length and batch size you intend to use.
Your next step
This planning estimate is within a base Mac mini's advertised memory tier, but real quantized files, cache and macOS usage may still prevent the model from fitting. Check the exact configuration.
Check this against a Mac mini configuration →Open the full RAM and VRAM calculator → for the method, the caveats, and how it differs from the artifact-based compatibility checker.
What changes for Llama
Context length affects cache memory independently from weight memory. Meta documents 128k context for the Llama 3.1 family and for the text-only Llama 3.2 1B/3B models, so long-context workloads need substantially more headroom than a short-prompt weight-fit calculation.
Weight fit is not the same as deployment fit
- Check the exact GGUF, safetensors, AWQ, GPTQ or runtime-specific artifact you will load.
- Reserve memory for KV cache, runtime allocations, the operating system and concurrent requests.
- Unified-memory Macs share the same pool with the OS and applications; discrete-GPU systems still need system RAM.
- For MoE models, active parameters reduce compute per token but do not automatically remove inactive expert weights from memory.
Sources
- Meta Llama 3.2 3B model card— 1.23B and 3.21B text-model parameter counts and context information
- Meta Llama 3.1 model card— 8B, 70B and 405B family sizes and 128k context
Agent Infrastructure Recommendation Kit
Sizing infrastructure for Llama?
Use the Agent Infrastructure Recommendation Kit to carry these memory assumptions into a documented local-vs-cloud infrastructure decision with explicit evidence and verification steps.
Get the Recommendation Kit — $19