Local AI sizing
Local AI RAM Requirements: What Actually Determines Memory Use?
Local AI memory requirements depend on model weights, quantization, context/KV cache, runtime overhead and concurrency. Size each component explicitly and leave headroom rather than treating parameter count as the final RAM requirement.
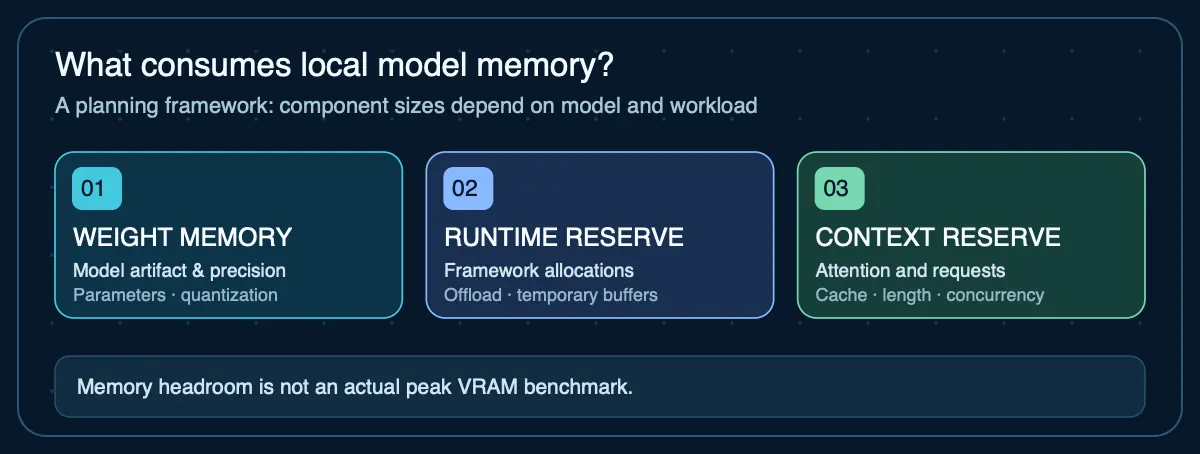
Model weights are the starting point, not the total
Lower-precision weights reduce memory pressure. Hugging Face documents 8-bit quantization as roughly halving weight memory and 4-bit quantization as compressing further. Real inference still needs memory beyond the weights.
Context length consumes memory too
The KV cache grows with context and workload. Long conversations, retrieved documents and tool traces can push an agent well beyond a short benchmark prompt. Ollama also documents that parallel processing increases context allocation.
RAM, VRAM and unified memory are different architectures
Discrete GPUs have device memory while Apple silicon exposes unified memory shared across the system. Reserve capacity for the operating system, agent runtime and other applications rather than assuming every advertised gigabyte is available to the model.
Size the memory for your model
Enter the model and precision you plan to run. The runtime reserve covers framework overhead; the context reserve is the memory you are setting aside for cache and concurrency.
Why context reserve is manual: exact attention-cache memory cannot be inferred safely from parameter count alone. For a real deployment, measure the specific model and runtime at the context length and batch size you intend to use.
Your next step
This planning estimate is within a base Mac mini's advertised memory tier, but real quantized files, cache and macOS usage may still prevent the model from fitting. Check the exact configuration.
Check this against a Mac mini configuration →Open the full RAM and VRAM calculator → for the method, the caveats, and how it differs from the artifact-based compatibility checker.
Sources
- Hugging Face — bitsandbytes— Quantization and memory guidance
- Ollama — FAQ— Runtime memory, context and concurrency behavior
Agent Infrastructure Recommendation Kit
Document the assumptions behind your local AI sizing
The Agent Infrastructure Recommendation Kit gives you a six-step system to define requirements, estimate capacity, compare local, cloud, VPS, GPU, and hybrid options, document evidence, and make the recommendation.
Get the Recommendation Kit — $19