Agent infrastructure
AI Agent Server Requirements for 24/7 Workloads
An AI agent server needs enough CPU and RAM for the runtime, tools and concurrent jobs; persistent storage for state and logs; reliable networking; and supervision, backups and recovery for 24/7 operation. A GPU is required only when the server also performs model inference that benefits from GPU acceleration.
CPU and RAM requirements depend on what the agent does
An API-orchestrating agent can have modest compute needs compared with a server performing local LLM inference. Browser automation, parallel workers, document processing and local databases can still make CPU and RAM important. Size the runtime and model as separate workloads before combining them.
A GPU is not automatically an agent requirement
If the agent calls a remote model API, its host may not need a GPU. If the same machine serves a local model, GPU or unified-memory capacity becomes part of model sizing. This distinction avoids paying for inference hardware when the host only needs reliable orchestration.
24/7 means operational requirements, not just compute
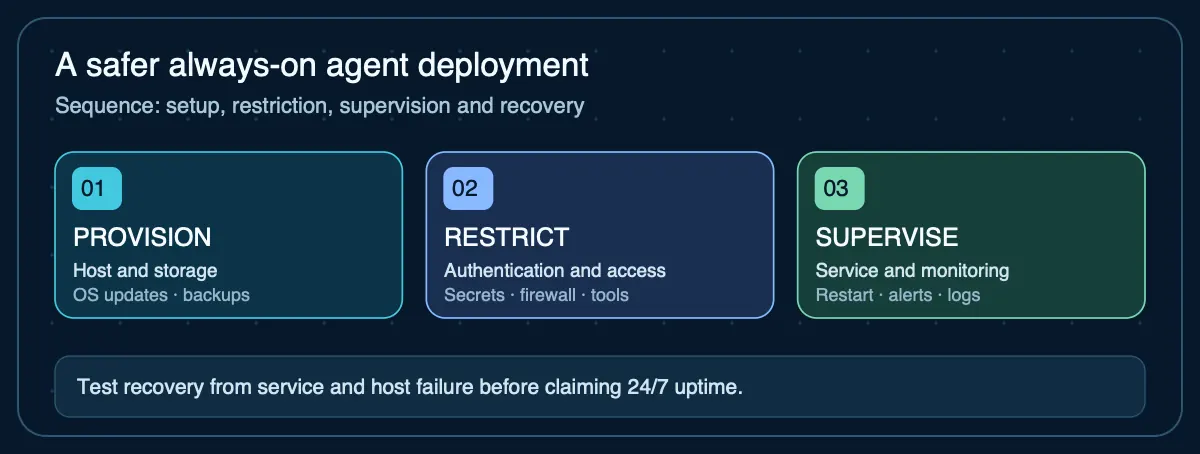
Persistent agents need process supervision, durable state, logs, backups, restart behavior, least-privilege credentials and monitoring. Storage and network reliability can matter more than peak CPU for an agent that mostly waits on APIs.
Price the server these requirements describe
Enter your own current prices. A host that only orchestrates an API model is priced as a VPS; a host that also serves inference is priced as GPU cloud or local hardware.
Your next step
The estimate prices a VPS, so the remaining question is whether the plan meets the persistence, recovery and resource requirements of a continuously running agent.
Review AI-agent VPS requirements →Open the full hosting cost calculator → for the formula and what the estimate deliberately leaves out.
Sources
- OpenClaw — installation— Self-hosted agent deployment patterns
- Hermes Agent — installation— Local and Linux agent installation patterns
- Ollama — FAQ— Local-model memory and concurrency when inference is colocated
Agent Infrastructure Recommendation Kit
Turn server requirements into a defensible architecture recommendation
The Agent Infrastructure Recommendation Kit gives you a six-step system to define requirements, estimate capacity, compare local, cloud, VPS, GPU, and hybrid options, document evidence, and make the recommendation.
Get the Recommendation Kit — $19